Sampler
def Sampler(
    smp_areas:geopandas.geodataframe.GeoDataFrame, # Areas to sample from, such as the output of `gridder`, indexed by `loc_id`
):
Draw random sample locations inside the areas of smp_areas.
def Sampler(
smp_areas:geopandas.geodataframe.GeoDataFrame, # Areas to sample from, such as the output of `gridder`, indexed by `loc_id`
):Draw random sample locations inside the areas of smp_areas.
def sample(
    n:numpy.ndarray, # Number of points to draw in each area, in `smp_areas` order
    **kwargs
)->geopandas.geodataframe.GeoDataFrame: # One `MultiPoint` per area, indexed by `loc_id`. Areas with `n` of 0 are left out
Draw n random points inside each area.
Build a grid of areas with gridder, then draw a random number of points in each area. Passing rng=0 makes the draw reproducible:
fname_raster = './files/ground-truth-02-4326-simulated.tif'
gdf_grid = gridder(fname_raster, nrows=10, ncols=10)
sampler = Sampler(gdf_grid)
n = np.random.default_rng(0).integers(0, 10, size=len(gdf_grid))
gdf_samples = sampler.sample(n, method='uniform', rng=0)
test_eq(len(gdf_samples), (n > 0).sum())
gdf_samples.head()| geometry | |
|---|---|
| loc_id | |
| 0 | MULTIPOINT ((-1.18953 43.0127), (-1.20911 43.0... |
| 1 | MULTIPOINT ((-1.22262 43.06251), (-1.18013 43.... |
| 2 | MULTIPOINT ((-1.18953 43.09751), (-1.22131 43.... |
| 3 | MULTIPOINT ((-1.20911 43.10122), (-1.18953 43.... |
| 4 | MULTIPOINT ((-1.18953 43.13702), (-1.22131 43.... |
ax = gdf_samples.plot(markersize=1, color=red)
gdf_grid.boundary.plot(ax=ax, color=black, lw=0.5)
ax.axis('off');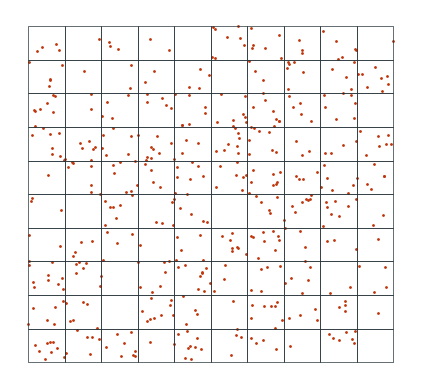
def rank_to_sample(
    ranks:numpy.ndarray, # Rank of each area, in `loc_id` order. Rank 1 is the highest priority
    budget:int, # Total number of samples to allocate
    min:int=0, # Minimum number of samples per area
    policy:str='Weighted', # Allocation policy: `Weighted` or `quantiles`
)->numpy.ndarray: # Number of samples for each area, in the order of `ranks`
Split budget samples across areas according to their ranks.
rank_to_sample connects Optimizer.get_rank to Sampler.sample. It turns each area’s rank into the number of points to draw there. The examples below use 8 areas ranked from 1 to 8 and a budget of 80 samples:
ranks = np.arange(1, 9)The Weighted policy gives each area a share of the budget proportional to 1/rank, rounded to the nearest integer:
n = rank_to_sample(ranks, budget=80)
test_eq(n, [29, 15, 10, 7, 6, 5, 4, 4])
n
array([29, 15, 10, 7, 6, 5, 4, 4])The quantiles policy splits the areas into four quartiles by rank. The first quartile shares 50% of the budget, the second 30%, the third 20% and the last none:
n = rank_to_sample(ranks, budget=80, policy='quantiles')
test_eq(n, [20, 20, 12, 12, 8, 8, 0, 0])
n
array([20, 20, 12, 12, 8, 8, 0, 0])min raises every area to at least that many samples. The total can then exceed budget, because rank_to_sample does not take the extra samples from other areas. Rounding can also make the total differ slightly from budget:
test_eq(rank_to_sample(ranks, budget=80, min=1, policy='quantiles').sum(), 82)